The newsletter · Wednesday 23 September 2026
Which Match Are You Watching?
A 62% forecast means losing 38 of 100. Markus Bernhardt and I on AI numbers nobody owns, and a pilot that landed at half its target and succeeded.
One signal 📡 One subtraction ➖ One analogy 🎾
Created by Sam Rogers of Snap Synapse | Episode 13 with cohost Markus Bernhardt | The Sunday newsletter of the weekly show | originally published at sigsub.show
The test this week. Take one number an AI hands your team and turn it into a hundred cases. How many go wrong, and whose desk do they land on? If nobody can name the desk, nobody owns the misses.
🎾 Analogy of the Week: Which Match Are You Watching?
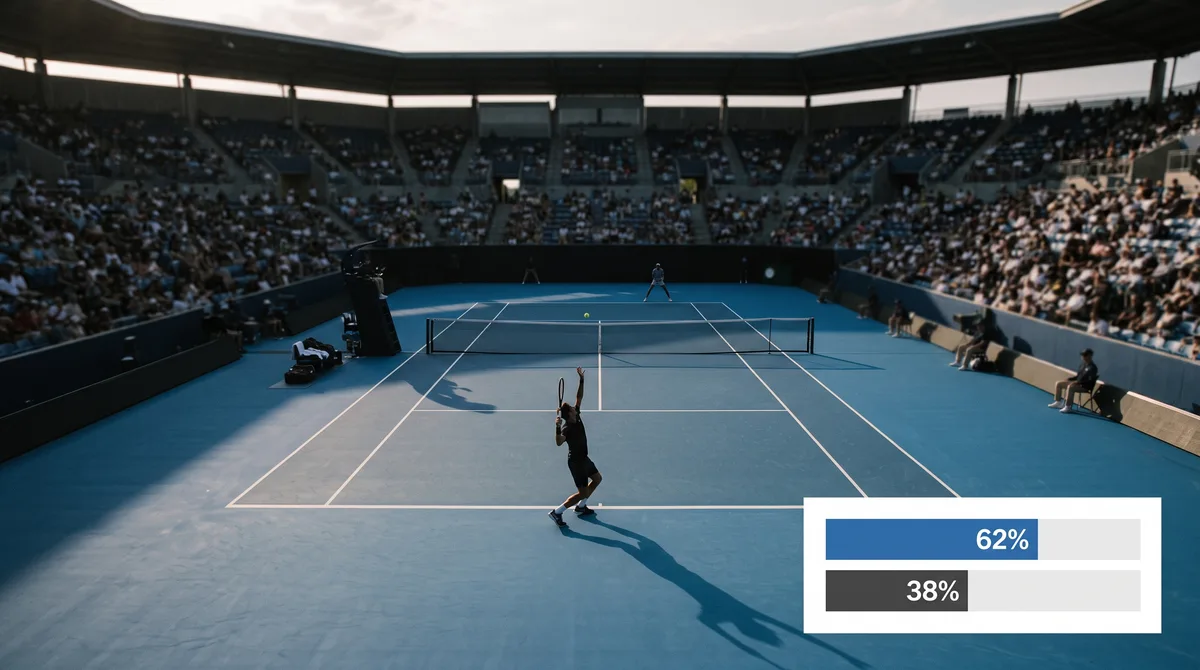
My show cohost this week, Markus Bernhardt, pointed out that you can't watch the US Open anymore without IBM Watson butting in and telling you (early in the match) who's going to win. Say it puts one player at 62%. Markus is astonished by how many people take that as a verdict, because "this is an intelligent AI system, it will know what it's talking about."
Here's what it actually says. Play that match a hundred times and that player loses 38 of them. "And you're trying to figure out which game you're watching."
The forecast can be exactly right and still tell you nothing about the match in front of you. That's not a flaw in the model. It's what a probability is.
A forecast is a claim about a hundred matches. You only ever get to watch one.
📡 Signal: The numbers are arriving before their owners
A classifier I was testing this week gave me a wrong answer at 95% confidence, so "only trust the confident ones" wouldn't have caught it. Then, once the results were in, moving my cutoff three points would have made every test pass, with no evidence for the move except that the tests passed. I left it where it was.
That cutoff is the part worth watching. More of the AI we're buying gives an answer and a number, and somebody decides where the line goes. Above it, act. Below it, don't. That line is a default. It usually gets set once, by whoever's most comfortable with the tool, and everyone downstream inherits it as if it were a fact. It's actually a policy about which mistakes we're willing to live with.
Even working exactly as designed, a 95% system gets five of every hundred dead wrong. "The numbers are arriving faster than the people who should own them."
▶️ Watch, read, or listen
Watch the full episode on YouTube, or find every format including the transcript at sigsub.show/episodes/ep-013. Also on Substack and LinkedIn.
Jump to a segment: 95% confident and wrong · 62% likely to win · finger in the wind · someone clever will say
➖ Subtraction: Stop grading a pilot against the number you guessed first
Markus's subtraction is the same mistake, made with a target instead of a forecast.
An insurance company he worked with set out to automate its small claims, under $150. At the kickoff, "finger in the wind," the team guessed 15 to 20% automation. Then they did the real work: documented the workflows, built a rules-based automation, and ran it alongside the human team for three weeks without letting it act. They learned where it was unbelievably good, where it fell down, and where the humans were less consistent than anyone had assumed.
They landed, highly confident, at 7 to 8%. That's when "someone clever will say, But we aim for fifteen to twenty."
Run the hundred test on it instead. Of every hundred small claims, seven or eight now run on their own, and the rest still land on the desks of a team that now understands automation far better than before, where "no one has been let go." That's not half a goal. It's a team ready for the next 10%.
A target set before the data is a destination, not a verdict.
🧭 Put It to Work
Run the hundred test on one number your team acts on this week: a confidence score, a pilot target, a dashboard accuracy figure. A resume screen that's 90% accurate misjudges ten of every hundred candidates. Whose desk do those ten land on? If the misses have no desk, the number has no owner, and usually that's because nobody chose the line on purpose. It came with the tool.
The Default Ledger, this episode's takeaway, lists each of those settings in a row that ends with the name of whoever set it, and leaves the name blank when nobody knows. Every episode has a takeaway, fourteen so far at sigsub.show/takeaways. Markus's brief The Decisions Your AI Is Making Without You goes even deeper.
Then the choice this episode can help with. Who in your organization is actually setting the AI defaults everyone else inherits, and what would it take to move that decision somewhere else? Or start smaller: Name one AI default in your org you did not choose and cannot change. Who set it? Send me your answer, or bring it to the show.
Until then,
Sam Rogers Game, Set, Match
New here? Subscribe at sigsub.show and the next episode lands in your inbox.
This week's cohost: Markus Bernhardt of Endeavor Intelligence and editor of the Endeavor Report.
Related reading:
- Measuring 500 Nuclear Engineers (064): the flip test writes down, before a pilot, the number that would change the decision. A guessed target is not that number, and treating it as one would have killed Markus's success.
- No Wrong Answers (067): decide what "good enough" means before you see the output, which is why the cutoff stayed put.
Get the next one
Free weekly newsletter on Substack. No account needed.
One signal, one subtraction, one analogy, every Sunday. Every issue, back to 001.